
Introduction
Microservices architecture solves the monolith scaling problem and immediately creates a new one: how do all these services actually talk to each other without everything falling apart? Most teams discover that choosing the wrong communication pattern, whether synchronous REST calls chained five layers deep or a message bus nobody can debug, causes more production incidents than the original monolithic bottleneck ever did. The real engineering challenge is not splitting your application into services; it is designing the communication topology so that failures stay isolated, latency stays predictable, and your team can still reason about what is happening at 3 AM during an outage. This post breaks down the core microservices communication patterns with clear trade-offs, concrete scenarios, and a decision framework built for teams operating at real scale.
Synchronous Communication: When Direct Calls Make Sense
Synchronous request-response is the most intuitive pattern in distributed systems architecture. One service calls another, waits for a response, and proceeds. It maps cleanly to how developers already think about function calls, which is exactly why teams default to it and exactly why it becomes a problem at scale. The question is not whether synchronous communication is bad. It is whether your specific use case can tolerate the coupling and latency it introduces.
REST and gRPC: Choosing the Right Protocol
The choice between REST and gRPC is not about which protocol is "better" in the abstract. It depends on the shape of your traffic and the contracts between your services. Here is how the two compare across the dimensions that actually matter in production:
Latency sensitivity: gRPC uses HTTP/2 multiplexing and Protocol Buffers, delivering significantly lower per-call overhead, making it the clear winner for internal service-to-service calls where milliseconds compound
Schema enforcement: gRPC enforces strict contracts through .proto files, catching breaking changes at compile time rather than in production, while REST relies on conventions and documentation that drift over time
Debugging and tooling: REST payloads are human-readable JSON you can inspect with curl, whereas gRPC requires specialized tooling like grpcurl or Bloom RPC, increasing the onboarding cost for new team members
Browser compatibility: REST works natively in browsers, making it the default for public-facing API endpoints, while gRPC requires a proxy layer like gRPC-Web for frontend consumption
Ecosystem maturity: REST has decades of tooling, middleware, and community knowledge; gRPC is catching up fast, but still has gaps in observability integrations and gateway support
For most teams, the pragmatic answer is to use gRPC for internal service-to-service calls where you control both ends, and REST for external APIs. Trying to standardize on one protocol across all boundaries usually creates more friction than it resolves. A deeper comparison of communication styles in microservice architecture can help clarify where each protocol fits.
The Cascading Failure Problem
Synchronous communication creates temporal coupling. Service A cannot proceed until Service B responds. If Service B is slow or down, Service A blocks, its thread pool fills up, and every upstream caller experiences the same degradation. This is how a single slow database query in one service takes down an entire checkout flow.
Resilience patterns like circuit breakers, timeouts, and bulkheads are not optional add-ons for synchronous microservices communication. They are structural requirements. Without them, every synchronous call is a distributed single point of failure. Teams that skip these patterns end up spending more time on post-mortem reviews than on feature development. The verdict: synchronous communication works well for simple, low-fan-out request paths where latency is acceptable and the called service has strong uptime guarantees. Beyond that, you need asynchronous patterns.
Asynchronous Communication: Event-Driven Patterns for Real Scale
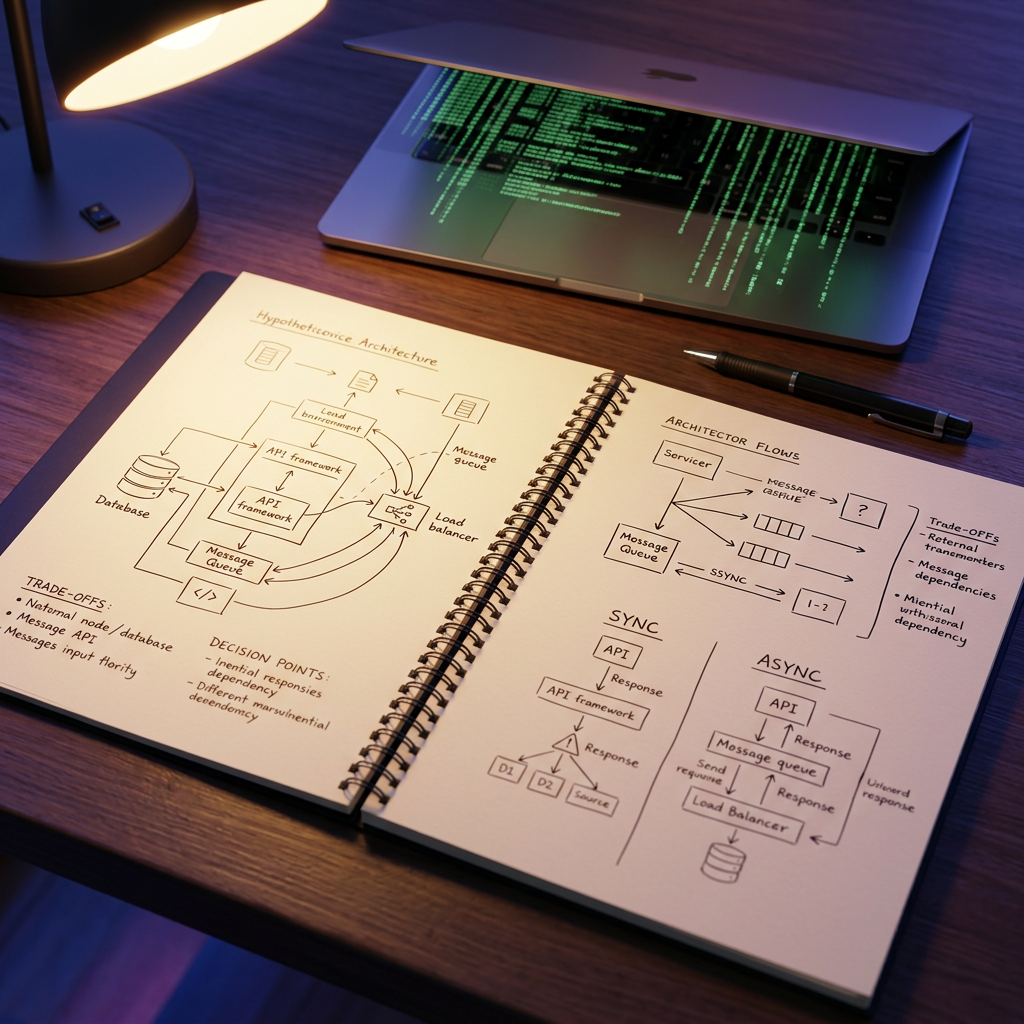
Asynchronous messaging decouples the sender from the receiver. A service publishes a message or event and moves on without waiting for a response. This is the foundation of event-driven microservices, and it is where most teams unlock genuine microservices scalability. But async introduces its own complexity: eventual consistency, message ordering, duplicate delivery, and the challenge of understanding what is actually happening across dozens of services emitting events.
Choreography vs. Orchestration: The Core Decision
This is the most consequential design decision in any async microservices system, and getting it wrong is expensive to reverse. In choreography, each service listens for events and decides independently what to do next. There is no central coordinator. In orchestration, a dedicated service (the orchestrator) explicitly tells other services what to do and in what order.
Choreography scales better for mid-size systems because it eliminates the orchestrator as a bottleneck and single point of failure. Each service owns its own logic, deploys independently, and can evolve without coordinating with a central controller. This maps well to domain-driven design principles where bounded contexts operate autonomously. However, choreography collapses without proper observability. When ten services react to events in a chain, and something goes wrong, tracing the root cause without distributed tracing is nearly impossible. Investment in OpenTelemetry and structured observability is a prerequisite, not a nice-to-have.
Orchestration makes sense when you have complex, multi-step workflows with compensating transactions, like payment processing or order fulfillment, where you need explicit control over the sequence and error handling. Tools like Temporal, Step Functions, or Conductor provide durable execution guarantees that pure choreography cannot match. The trade-off is that the orchestrator becomes a critical dependency that your team must operate and scale independently.
Message Brokers and the Delivery Guarantee Spectrum
The choice of message broker shapes your entire system's reliability profile. Apache Kafka provides durable, ordered, replayable event logs, making it ideal for event sourcing and systems where consumers need to catch up after downtime. RabbitMQ excels at task distribution with flexible routing, but does not provide the same replay guarantees. Cloud-native options like AWS SQS/SNS or Google Pub/Sub reduce operational burden but introduce vendor coupling.
The most common mistake teams make is treating message delivery as a solved problem. "At-least-once" delivery means your consumers must be idempotent, and that constraint ripples through your entire data model and API design. "Exactly-once" semantics, where they exist, come with significant throughput penalties. Understanding these trade-offs before committing to a broker saves weeks of debugging in production. For teams evaluating system design trade-offs, this is one of the highest-leverage decisions to get right early.
API Gateways and Service Meshes: Picking the Right Abstraction Layer
Both API gateways and service meshes sit between your services and manage cross-cutting concerns like routing, authentication, rate limiting, and observability. But they operate at different layers and solve different problems. Conflating them is one of the most common and costly mistakes in microservices design patterns.
When an API Gateway Is Enough
An API gateway in microservices sits at the edge of your system and handles north-south traffic: requests coming from external clients into your service mesh. It manages authentication, request routing, rate limiting, and protocol translation. For most teams with fewer than 20 services, a well-configured API gateway (Kong, AWS API Gateway, or the Kubernetes Gateway API) handles the vast majority of cross-cutting concerns without the operational overhead of a full service mesh.
The key insight is that an API gateway does not require sidecar proxies, does not add per-hop latency to internal calls, and does not demand a dedicated platform team to operate. If your primary pain points are external traffic management, API versioning, and centralized auth, an API gateway solves them cleanly. Reaching for a service mesh at this stage is premature optimization that slows teams down rather than speeding them up.
When Service Mesh Architecture Becomes Necessary
A service mesh manages east-west traffic: the internal communication between your services. It injects sidecar proxies (like Envoy) alongside each service instance to handle mutual TLS, traffic shaping, retries, circuit breaking, and fine-grained observability, all without requiring changes to your application code.
Service mesh architecture earns its complexity when you have 30+ services, multiple teams deploying independently, strict security requirements for inter-service encryption, and a need for traffic management features like canary deployments or traffic mirroring at the network layer. Istio and Linkerd are the leading options, with Linkerd offering a significantly simpler operational profile at the cost of fewer features. Teams building their developer toolchain should evaluate whether their service count and security posture genuinely demand this level of infrastructure before adopting it.
A Decision Framework for Choosing Communication Patterns
Picking the right microservices communication pattern is not about following best practices from a conference talk. It is about matching the pattern to your team's actual operational reality. The following framework distills the trade-offs discussed above into a practical decision tree.
Team Size and Operational Maturity
Small teams (under 10 engineers) should default to synchronous REST with an API gateway and introduce async messaging only for specific, well-understood use cases like background processing or notifications. The observability and debugging overhead of a fully event-driven system exceeds what a small team can reasonably manage. Mid-size teams (10-50 engineers) benefit most from clean architectural boundaries with choreography-based async for cross-domain communication and synchronous calls within bounded contexts.
Large organizations (50+ engineers across multiple teams) typically need a mix: orchestration for complex business workflows, choreography for domain events, synchronous gRPC for latency-sensitive internal calls, and a service mesh to manage the cross-cutting concerns that would otherwise drown every team in boilerplate. The platform team operating the mesh must be funded and staffed accordingly, not treated as a side project.
Latency and Failure Tolerance
If your use case requires sub-100ms responses and cannot tolerate eventual consistency (real-time pricing, authentication, session validation), synchronous communication is the right choice, hardened with circuit breakers and aggressive timeouts. If your use case can tolerate seconds or minutes of delay and values durability over speed (order processing, analytics pipelines, notification delivery), async messaging is the clear winner. The resources available through communities at DevvPro can help engineering teams reason through these exact trade-offs with practical case studies.
Most real systems need both. The mistake is trying to standardize on one pattern for everything. The best architectures acknowledge that different communication paths within the same system have different requirements and choose accordingly. Treating technical debt as a design choice means consciously accepting the operational cost of each pattern you adopt, rather than discovering it during an incident.
Conclusion
Microservices communication is where distributed systems architecture gets real. The patterns themselves are well-documented, but the decision of which pattern to apply where, and at what scale, separates resilient systems from fragile ones. Default to the simplest pattern that meets your actual requirements, invest in observability before you invest in complexity, and resist the urge to adopt every tool you see at a conference. DevvPro covers these architectural decisions regularly for engineering teams navigating exactly these challenges. The right communication topology is not the most sophisticated one; it is the one your team can operate, debug, and evolve with confidence.
Explore more engineering deep dives and architectural guides at DevvPro.
Frequently Asked Questions (FAQs)
What are the challenges of microservices communication?
The primary challenges include network latency, partial failures, data consistency across services, debugging distributed call chains, and choosing between synchronous and asynchronous patterns that match your team's operational maturity.
How do you handle microservices communication at scale?
At scale, teams typically combine synchronous calls for latency-sensitive paths with asynchronous event-driven messaging for cross-domain workflows, supported by robust observability, circuit breakers, and idempotent consumers.
What is service mesh, and when should you use it?
A service mesh is an infrastructure layer that manages internal service-to-service communication through sidecar proxies, handling concerns like mutual TLS, retries, and traffic shaping, and it becomes necessary when you operate 30 or more services with strict security and traffic management requirements.
What is an API gateway in microservices?
An API gateway is an edge component that manages external client requests by handling authentication, rate limiting, routing, and protocol translation before forwarding traffic to internal services.
How to scale microservices effectively?
Effective scaling requires matching communication patterns to specific latency and consistency requirements, investing in observability tooling early, and ensuring each service can be deployed, scaled, and debugged independently without tight coupling to other services.